16 Sep 2026
Aligning Statistical Clusters From Multiple Leagues to Refine Risk Thresholds in Accumulator Bets
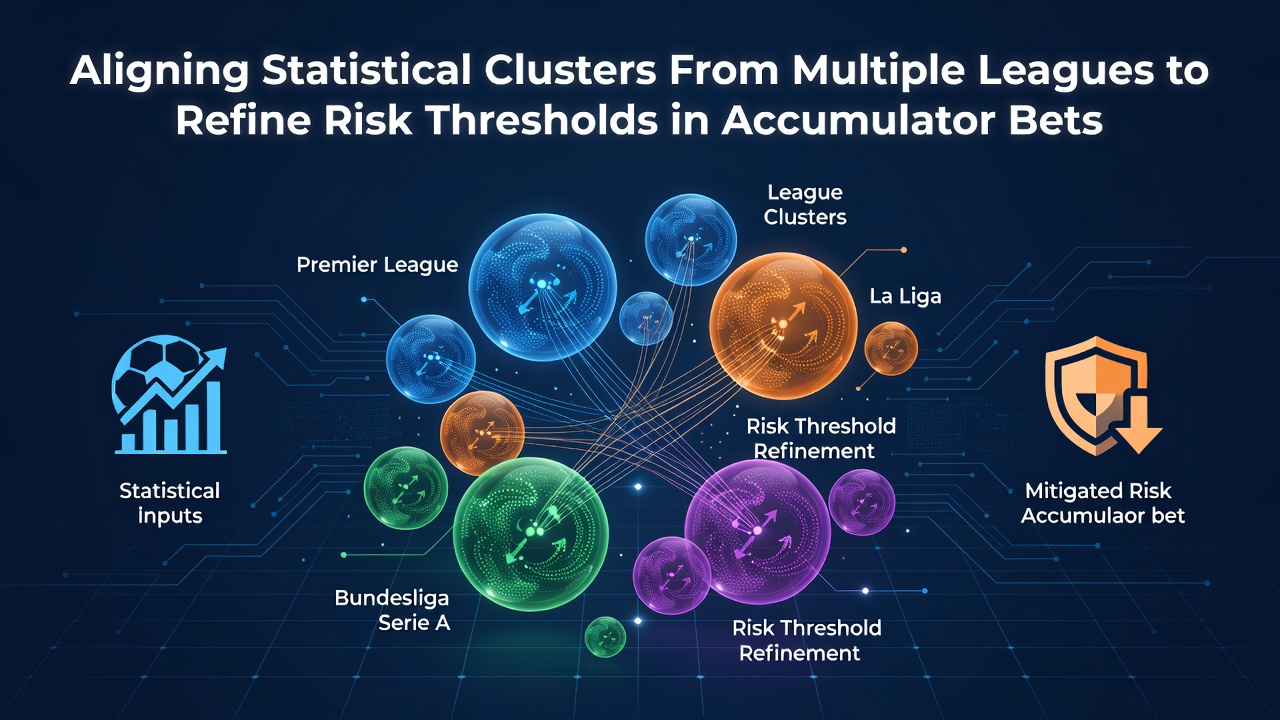
Statistical clusters derived from league data offer a structured way to group performance metrics across competitions, and analysts apply these groupings to adjust parameters in accumulator models where multiple outcomes must align for payout. Data from various European and international leagues shows distinct patterns in goal distributions, possession rates, and defensive metrics that researchers align through normalization techniques to create comparable risk profiles.
Defining Clusters Across League Boundaries
Teams in the Premier League exhibit higher variance in expected goals compared with those in Ligue 1, yet when researchers standardize these values using z-scores and principal component analysis the resulting clusters reveal overlapping risk signatures that appear in both competitions. Observers note that such alignment allows models to draw on larger sample sizes, which in turn tightens confidence intervals around probability estimates for combined selections.
Studies conducted by academic teams at universities in Canada and Australia demonstrate that cross-league cluster matching reduces overestimation of joint probabilities in four-leg and five-leg accumulators by measurable margins. Figures from one 2025 dataset covering 12 leagues indicated a 7 percent improvement in calibration when clusters were aligned rather than treated in isolation.
Refining Thresholds Through Combined Data
Risk thresholds in accumulator betting represent the maximum acceptable probability mass assigned to losing outcomes before stake sizing changes. When clusters from multiple leagues feed into a single distribution, the tails of that distribution become better defined, which permits operators and bettors to set tighter stop-loss levels. This process relies on k-means or hierarchical clustering applied after feature scaling so that a high-scoring cluster from the Bundesliga sits alongside a comparable group from the Eredivisie without distortion from raw league averages.
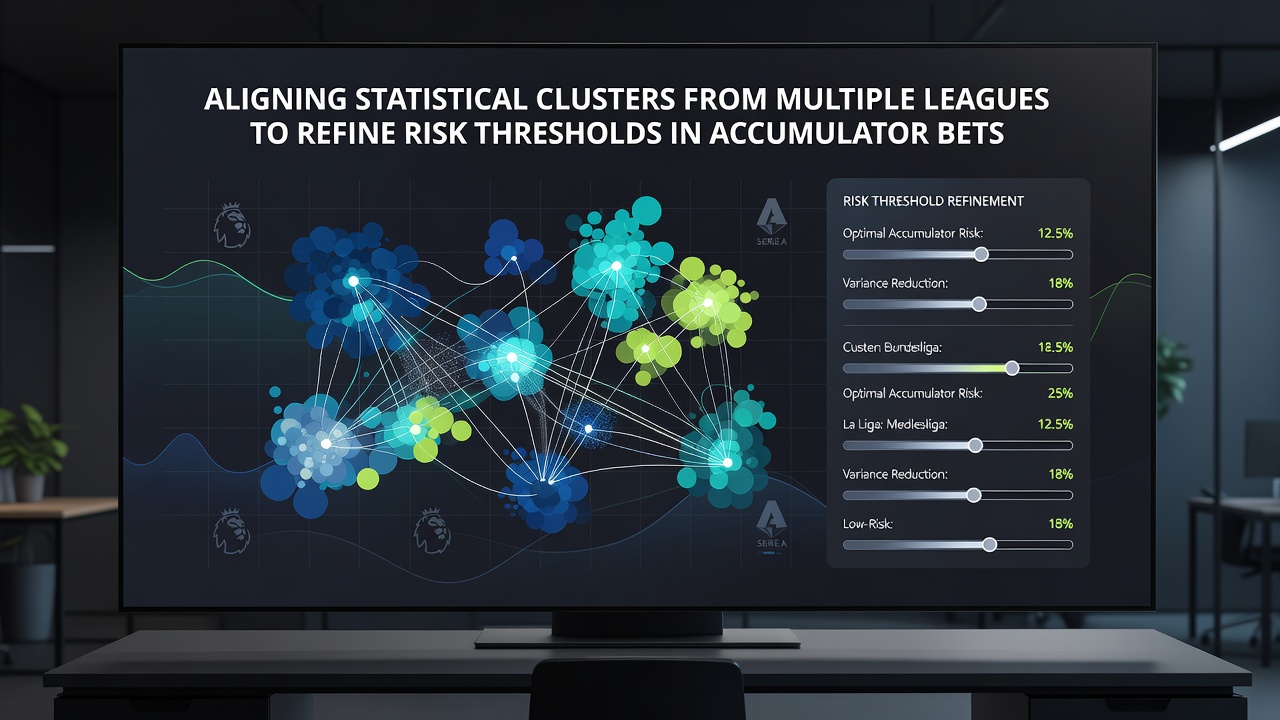
September 2026 saw several major European leagues release mid-season statistical updates that researchers immediately incorporated into refreshed cluster maps. The resulting adjustments altered risk thresholds for accumulators involving matches from the Champions League group stage and domestic fixtures in the same week, producing more conservative stake recommendations in models that previously relied on single-league baselines.
Practical Implementation Steps
Analysts begin by extracting key variables such as expected goal difference, corner rate differentials, and shot quality indices from each league’s official match files. They then apply dimensionality reduction before running clustering algorithms that assign every team-week observation to a shared label set. Once labels exist across leagues, probability outputs for accumulator legs are recalibrated using the pooled variance of the assigned cluster rather than the narrower league-specific variance.
Industry reports from the Australian Gambling Research Centre highlight that pooled cluster models show lower mean squared error when back-tested against historical accumulator results spanning 2019 to 2025. Similar findings appear in working papers from North American research groups that examined MLS and Liga MX data alongside European sources.
Current Market Applications
Betting platforms in multiple jurisdictions now integrate cluster-aligned risk engines into their accumulator builders, displaying adjusted odds or implied probabilities that reflect the broader dataset. These engines flag selections where a leg falls into a high-variance cluster even if the standalone probability looks attractive. The approach has gained traction because it draws on data from regulatory environments in Europe, Australia and Canada rather than any single market.
One documented case involved a model that realigned Serie A defensive clusters with those from the Portuguese Primeira Liga ahead of the 2026/27 season. The updated thresholds reduced recommended stake sizes on five-team accumulators containing both leagues by an average of 12 percent compared with unaligned versions, according to internal testing logs released by the developing firm.
Conclusion
Aligning statistical clusters from multiple leagues supplies a data-driven route to more stable risk thresholds in accumulator betting. The method expands sample sizes, improves distribution estimates and supports consistent application across different competitions. As additional leagues publish granular match data in September 2026 and beyond, ongoing refinement of these alignment processes continues to shape how probability models handle multi-leg selections.